
DigitalOcean Inference Engine
DigitalOcean's managed inference: serverless LLM and image APIs, dedicated GPU endpoints and batch jobs
DigitalOcean Inference Engine is DigitalOcean's managed inference service. It offers serverless per-token APIs, dedicated GPU endpoints billed by the hour, batch jobs and a router that picks a model per request. Serverless covers OpenAI and Anthropic models plus open-weight models such as gpt-oss. Image models served through fal draw from the same prepaid balance.
Open models start at $0.05 per 1M input tokens (gpt-oss-20b). FLUX Schnell images cost $0.003 per megapixel. Dedicated endpoints start at $2.59 an hour on an AMD MI300X.
Pricing: Per token usage
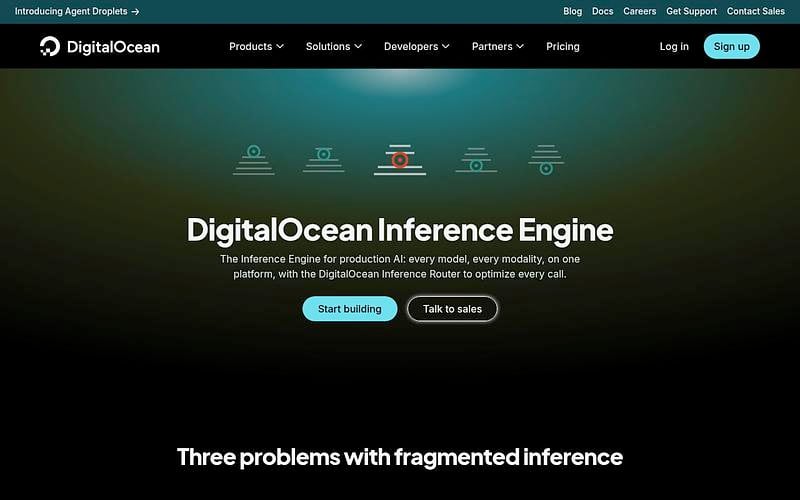
DigitalOcean Inference Engine prices by model
Per 1M tokens, read off DigitalOcean Inference Engine's own pricing page on the date shown.
| Model | Input / 1M | Cached / 1M | Output / 1M | Checked | Notes |
|---|---|---|---|---|---|
| gpt-oss-120b | $0.10 | – | $0.70 | 11 Oct 2026 | |
| gpt-oss-20b | $0.05 | – | $0.45 | 11 Oct 2026 |
DigitalOcean Inference Engine Alternatives
Explore 126 products in the Inference APIs category. View all DigitalOcean Inference Engine alternatives.

Heabsy
EU inference API on its own GPUs in the EEA, with zero data retention and OpenAI- and Anthropic-compatible endpoints.

DeepInfra
Run the top AI models using a simple API, pay per use. Low cost, scalable and production ready infrastructure.


Mistral
Use models in a few clicks with our platform. Download our open models for deep access.
Work on DigitalOcean Inference Engine? Feature it at the top of Inference APIs.
Is your product missing?